Prometheus Quantum Hypervisor

The QPU is part of
the computation.

Prometheus Quantum Hypervisor is the execution-intelligence layer developed by Prometheus Dynamics. It evaluates how a logical workload can be physically realized for a specific QPU, selects an execution candidate, and connects that decision to measured hardware results.

REAL HARDWARE·MULTI-QPU EVALUATION·VERIFIABLE EVIDENCE
Hardware-Aware Execution Layer
Secure Endpoint
33+
IBM hardware jobs in public record
1.62M+
Documented Hardware shots
3
IBM Heron QPUs Tested
7 / 9
Controlled comparisons improved
The Finding

Same logical circuit. Different QPU. Different result.

The controlled multi-QPU study submits an identical logical circuit simultaneously to Fez, Kingston, and Marrakesh. The measured physical result changes materially with the target processor, and the relative performance of the execution strategies can change with it.

Controlled 20Q broadcast

Target-QPU selection is measurable.

For the 20-qubit broadcast, each target QPU receives an identical logical circuit submitted simultaneously to Fez, Kingston, and Marrakesh. Each compiler receives the same 16,384-shot allocation, and the resulting physical executions are recorded from the corresponding IBM jobs.

IBM Fez

Observed fidelity

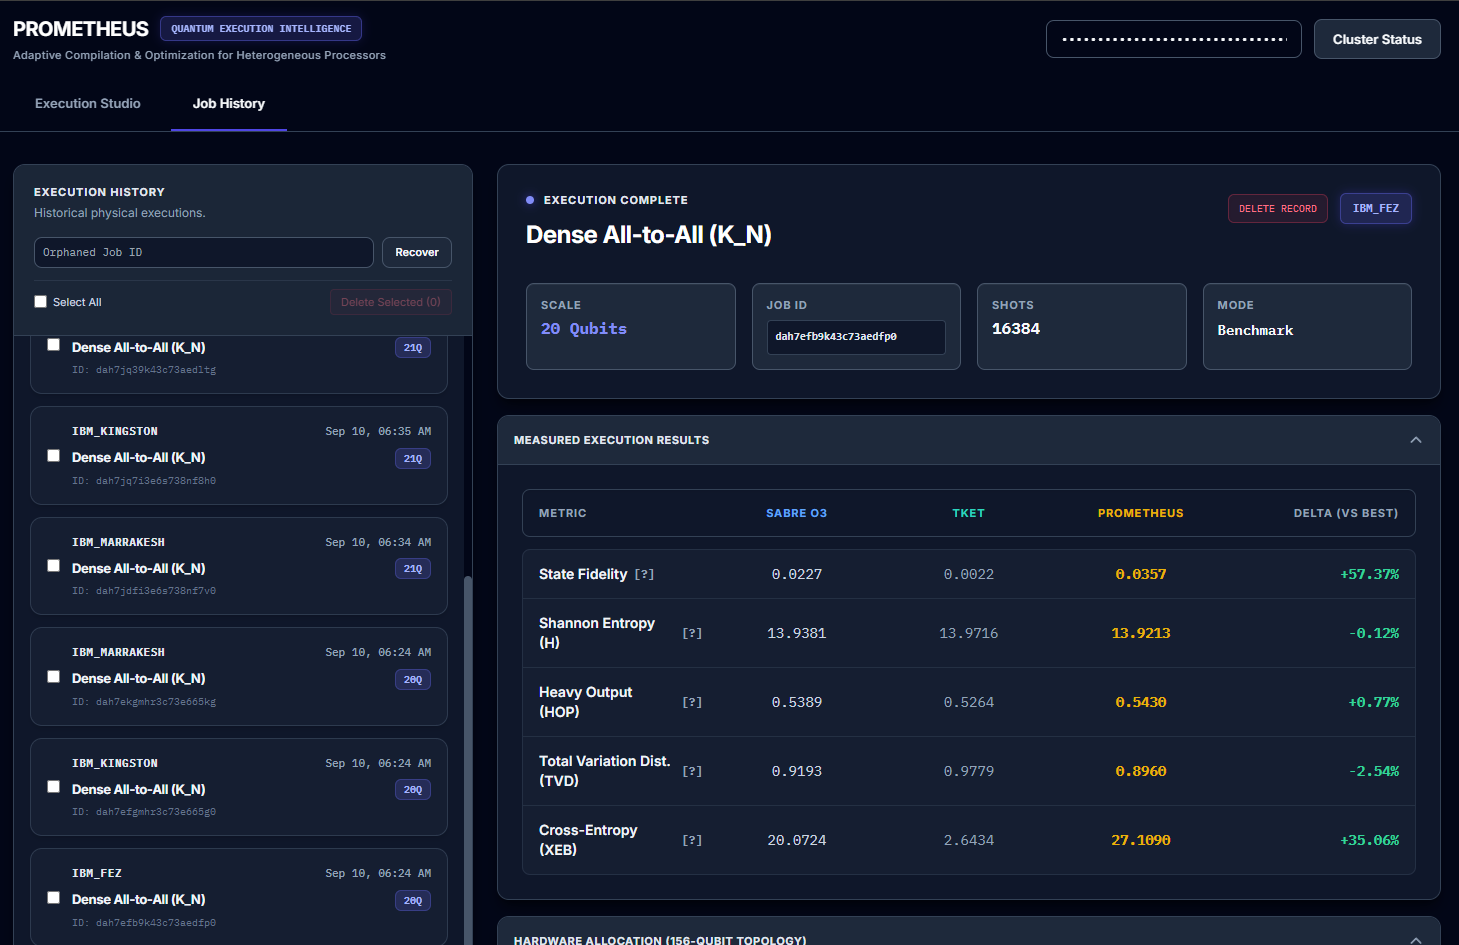
0.0357

Prometheus vs 0.0227 for SABRE O3 and 0.0022 for TKET.

Prom vs SABRE+57.4%
XEB27.1090
IBM Marrakesh

Observed fidelity

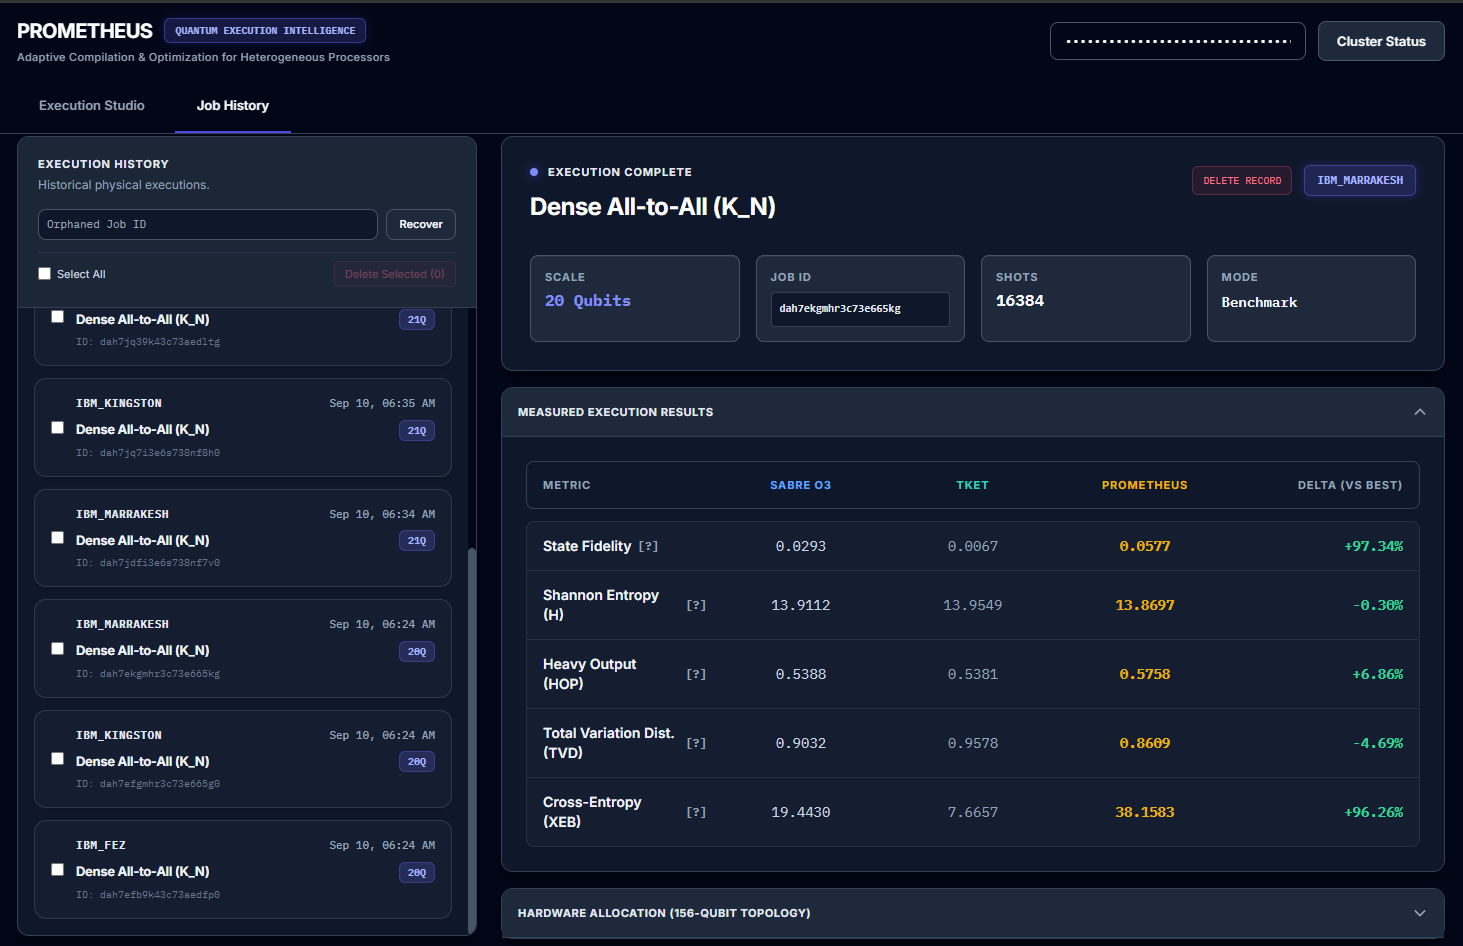
0.0577

Prometheus vs 0.0293 for SABRE O3 and 0.0067 for TKET.

Prom vs SABRE+97.3%
XEB38.1583
7 / 9Prometheus fidelity improved in 7 of 9 controlled 20–22Q comparisons
9 / 9Evidence packages cryptographically verified
16,384Shots per compiler on every controlled job
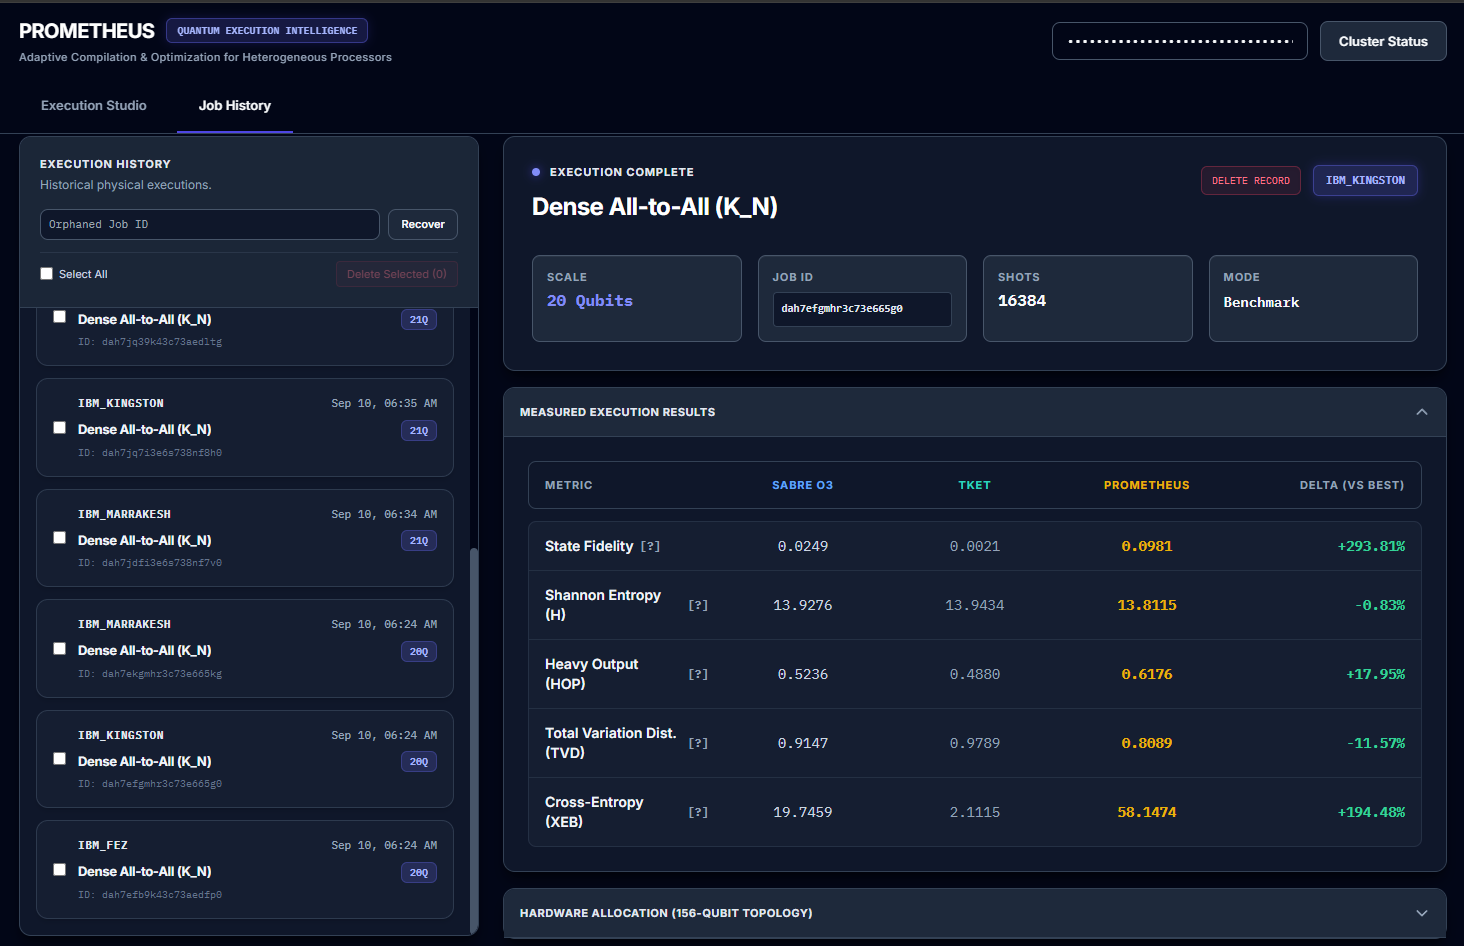
The important observation: the same workload class does not produce one fixed execution outcome. The measured Prometheus fidelity itself varies from 0.0357 on Fez to 0.0981 on Kingston and 0.0577 on Marrakesh, while the relative result versus conventional compilation changes with the target QPU.
Visual proof
Prometheus 20-qubit IBM Fez execution result screen
IBM Fez · 20QMeasured execution comparison and physical result record.
Prometheus 20-qubit IBM Kingston execution result screen
IBM Kingston · 20QThe same workload class produces a markedly different measured outcome.
Prometheus 20-qubit IBM Marrakesh execution result screen
IBM Marrakesh · 20QIndependent hardware execution record for the third target QPU.
Evidence integrity

The numbers are preserved as evidence, not just reported as claims.

Raw IBM job responses are preserved, packaged deterministically, fingerprinted with SHA-256, and verified through a separate integrity process. The public evidence record is designed so post-capture modification of the preserved artifacts is detectable.

01 · CaptureAuthenticated IBM job retrieval and raw response preservation.
02 · LockDeterministic evidence package generated from the preserved responses.
03 · HashSHA-256 fingerprints recorded for raw artifacts and packages.
04 · VerifyIndependent recomputation detects changes to the preserved evidence.
Why Quantum Teams Should Care

The value is the physical result.

Prometheus operates at the point where a logical circuit becomes a real hardware execution. That matters when the physical processor, workload structure, and compilation choice can materially change the measured result.

Dense all-to-all · 21Q · Marrakesh

The target QPU changes the outcome.

On Marrakesh, Prometheus reached 0.0904 fidelity while SABRE O3 reached 0.0641 for the same 21Q broadcast workload family.

+41.1%Prometheus vs SABRE fidelity
XEB: 394.4026 vs 277.0812 · 16,384 shots per compiler
Dense all-to-all · 22Q · Fez

Large structural differences can become physical differences.

Prometheus reached 0.0275 fidelity versus 0.0002 for SABRE O3 in the 22Q Fez broadcast result.

+5,389.6%Prometheus vs SABRE fidelity
XEB: 609.8650 vs 17.3120 · 16,384 shots per compiler
The Platform

An execution layer between software and hardware.

Prometheus sits around the compilation stack rather than exposing another general-purpose compiler as the product. It connects the logical workload to a specific physical processor, evaluates execution candidates, and keeps the proprietary selection mechanism protected.

Prometheus Quantum Hypervisor
The execution-intelligence layer developed by Prometheus Dynamics for turning logical workloads into hardware-aware physical execution strategies.
Execution Layer
Workload
Application stays above the hardware
Quantum workloads enter at the logical level while the execution system handles processor-specific concerns below the application.
Compilation
Compilation becomes an execution choice
Prometheus can evaluate multiple physical realizations rather than treating a single compiler output as the endpoint.
Hardware
Processor conditions inform placement
Hardware information can be incorporated into the selection of the physical execution used for the workload.
Execution
The chosen compilation reaches the QPU
The selected physical compilation is dispatched to real hardware and assessed through measured execution evidence.
01

Accept the workload

Start with the logical circuit and execution requirements.

02

Evaluate possibilities

Consider multiple compilation and routing paths for the target environment.

03

Coordinate with hardware

Incorporate hardware information into the physical compilation decision.

04

Dispatch and measure

Send the chosen physical compilation to the QPU and inspect the resulting measurements.

Measured Benchmark

Routing cost is not the whole problem.

A 9-qubit dense all-to-all graph forces a sparse processor to reconcile a highly connected logical workload with limited physical connectivity. This earlier single-job comparison shows how a different physical realization can change measured hardware outcomes.

Three execution strategies
SABRE O3 and TKET provide general-purpose compilation baselines. Prometheus evaluates physical execution candidates around the compilation process and selects a realization for dispatch.
Workload9-Qubit Dense (All-to-All) TargetIBM Marrakesh (156Q) PrimitiveSamplerV2 IBM jobdadl5jd1ierc738l1420
Single-Job Hardware Validation
SABRE O3
General-purpose routing baseline (IBM)
BASELINE

SABRE produced a valid routed circuit using 90 two-qubit gates and a physical depth of 145. Its measured state fidelity in this comparison was 0.5738.

Depth145
2Q gates90
State fidelity0.5738
HOP0.6975
TKET
General-purpose compilation baseline (Quantinuum)
BASELINE

TKET produced a valid physical circuit, but in this benchmark it required 123 two-qubit gates and reached a physical depth of 165. Its measured state fidelity was 0.5248.

Depth165
2Q gates123
State fidelity0.5248
HOP0.7339
Prometheus
Quantum execution hypervisor
SELECTED

Prometheus selected a different physical compilation with 74 two-qubit gates and a depth of 109. That execution produced a measured state fidelity of 0.7466.

Depth109
2Q gates74
State fidelity0.7466
HOP0.8425
Why the single-job design matters

The three compilation paths were evaluated through a single SamplerV2 hardware job on IBM Marrakesh rather than through separate jobs taken at different times. This controls for execution-window differences such as changing calibration conditions and timing between runs, keeping the comparison tied to one physical execution record.

Measured execution results
Metric
SABRE O3 (IBM)
TKET (Quantinuum)
PROMETHEUS
DELTA VS BEST BASELINE
Physical depth
145
165
109
−24.83%
Two-qubit gates
90
123
74
−17.78%
State fidelity
0.5738
0.5248
0.7466
+30.12%
Heavy Output Probability
0.6975
0.7339
0.8425
+14.80%
Total Variation Distance
0.4572
0.5241
0.3015
−34.04%
Cross-Entropy Benchmark
38.3213
31.1110
50.1079
+30.76%
Hardware-weighted cost
0.0510
0.0694
0.0318
−37.65%
ImprovementUnfavorable changeDelta is relative to the strongest baseline for each metric.
Research & Experimental Record

Built around a testable hardware question.

Prometheus grew out of real-hardware experiments examining how physical placement, routing cost, hardware conditions, and measured output interact. The public record contains five experimental programs, randomized instances, multi-QPU studies, IBM execution evidence, aggregate results, and explicit limitations.

5
Experimental programs in the public research record

The repository separates individual experiments so hypotheses can be tested under different workloads, scales, topologies, and physical processors.

A scientific development loop

Prometheus research does not assume that lower routing cost always means better hardware output. The experiments test that relationship directly, look for repeatability across randomized instances, examine scaling boundaries, and compare behavior across IBM Heron processors. The public record also retains mixed and negative outcomes rather than only favorable examples.

View the public research record →
01 · DISTRIBUTION

Distributional concentration

Tests whether physical routing cost and observed output-distribution behavior remain coupled on real hardware. One QFT-8 experiment on ibm_kingston showed a more concentrated output despite substantially greater physical routing cost.

QFT-8 · 100,000 shots · ibm_kingston
02 · ROBUSTNESS

Randomized instance robustness

Matched randomized QAOA and CrossEnt instances test whether observed behavior survives beyond manually selected circuits.

40 matched instances · N=6–9 · ibm_marrakesh
03 · SCALING

Micro-gradient scaling

Sweeps workload size and algorithm family to identify both favorable topological regimes and routing-penalty regimes rather than assuming that extra routing is always beneficial.

QFT / QAOA · scaling boundaries
04 · TOPOLOGY

Topological mapping

A 13-qubit topology-stress benchmark examined whether a substantially different physical realization could avoid the ground-state collapse observed in a depth-optimized baseline.

13 qubits · 80,064 shots · ibm_kingston
05 · MULTI-QPU

Three-QPU mechanistic sweep

Related workloads were examined across Fez, Kingston, and Marrakesh to test whether global device statistics are enough to describe the quality of a particular physical execution.

3 IBM Heron processors · workload-dependent study
Technical & Strategic Partnership

Turn the next experiment into an external evaluation.

The next stage is broader independent evaluation: real workloads, additional hardware, repeat measurements, technical integration, and the resources needed to move the system beyond an internal research program.

For technical evaluators

Bring a workload worth testing.

Prometheus can be evaluated against workloads that are sensitive to physical topology, routing, and hardware conditions. The goal is to determine where execution intelligence creates measurable value on workloads that matter outside the laboratory.

Technical evaluatorsRun controlled experiments, inspect the physical realization, and independently examine the underlying hardware evidence.
Platform teamsEvaluate an additional hardware-aware execution layer above existing compilation infrastructure.
Application teamsBring dense, routing-sensitive, or fidelity-limited workloads and measure actual QPU outcomes.
Strategic partnersProvide QPU access, technical collaboration, workload access, or capital for broader validation and product development.
The opportunity
The next evaluation should come from the people who intend to use the result.

Prometheus has an established real-hardware research record across multiple IBM processors and workload scales. The next step is external workloads, broader hardware coverage, repeat measurements, and independent hands-on evaluation.
Get Started

Request a technical evaluation.

UPLINK execution endpoints are currently restricted. External technical evaluation can be scoped around your workload, target hardware, and the level of evidence you need to inspect.

1

Define the workload

Start with a real logical workload, its execution objective, and the processors or hardware conditions you want evaluated.

2

Scope the evaluation

Agree on the comparison, target QPU, measurements, and evidence package appropriate for the evaluation.

3

Run on real hardware

Execute the selected workload through the evaluation environment and compare measured results against the agreed baseline.

4

Inspect the evidence

Review the physical realization, execution results, provenance, and preserved evidence associated with the evaluation.

Investor Brief · Commercial Thesis

Quantum infrastructure is expensive.
A lot of QPU time and resources are spent getting workloads onto hardware.

The industry's effective quantum computational capacity is not determined by the physical qubit count printed on the processor. It is determined by how much useful computation survives physical execution.

Industry Benchmark

Why Industry Leaders Struggle on Live Hardware

Both IBM (via SABRE O3) and Quantinuum (via TKET) have developed world-class general-purpose compilers. However, both stacks were engineered under a fundamental architectural assumption: they treat physical hardware as static geometry rather than an evolving, noisy environment.

IBM SABRE (Default Transpiler)

High Phase Decoherence

IBM's SABRE optimizes aggressively for mathematical circuit depth and physical gate counts, but assumes that all couplers on the heavy-hex lattice behave equally according to static calibration tables. When mapping dense, highly connected algorithms, SABRE frequently routes critical computational traffic directly through degraded physical couplers, causing fatal phase decoherence across long gate sequences.

Quantinuum TKET (Baseline)

Excessive SWAP Bloat

Quantinuum's TKET is exceptionally powerful at algebraic simplification and single-qubit rotation reduction. However, when confronted with complex, non-native multi-qubit graphs on sparse superconducting hardware, TKET's default architectural mapping passes generate massive, bloated SWAP gate chains. These chains rapidly push circuit execution duration beyond the hardware's coherence lifetime, collapsing the quantum state into uniform white noise.

The Prometheus Hypervisor Advantage

Adaptive Hardware-Graph Co-Design

Preserved Coherence

Prometheus does not treat compilation as a one-way translation step. It treats physical execution as a continuous optimization problem. By adaptively synthesizing physical topology around live hardware decay profiles, Prometheus selectively detours traffic away from critical path congestion. This minimizes idle spectator decoherence and ensures quantum phase coherence survives before the physical microwave pulses ever execute.

Empirical Verification

18-Node Complete Graph Multi-QPU Broadcast Benchmark

To demonstrate clear superiority over industry baselines, we broadcasted an identical, dense 18-node complete graph simultaneously across three distinct 156-qubit IBM Heron processors (Fez, Kingston, and Marrakesh). To ensure uncompromising scientific fairness, all compilers operated under identical shot allocations (16,384 shots) with uniform Twirled Readout Error Extinction (TREX) applied equally across all returned distributions.

Hardware Backend Observed Metric IBM Baseline (SABRE O3) Prometheus Hypervisor Net Physical Advantage
IBM Kingston
156-Qubit Heron QPU
Circuit Depth 370 layers 265 layers -105 Layers (-28.4%)
Two-Qubit Gates 439 gates 323 gates -116 Gates (-26.4%)
Physical State Fidelity 0.1819 0.2709 +48.92% Relative Improvement
IBM Marrakesh
156-Qubit Heron QPU
Circuit Depth 458 layers 330 layers -128 Layers (-27.9%)
Coupler Congestion 49.14 index 15.16 index -69.1% Congestion Relief
Physical State Fidelity 0.1037 0.1444 +39.20% Relative Improvement
IBM Fez
156-Qubit Heron QPU
Physical State Fidelity 0.1270 0.1362 +7.24% Relative Improvement
Core Insight: Error mitigation cannot reconstruct a signal once a quantum state has completely decohered into uniform white noise. By drastically reducing depth and eliminating high-error SWAP networks, Prometheus preserves the underlying physical signal so error mitigation techniques can actually function.
Tier 1 · Software & API

SaaS Execution Optimizer

Usage-based subscription for enterprise quantum research labs, financial institutions, and pharmaceutical teams. Charges per compilation pass based on physical risk reduction and depth elimination.

Tier 2 · Enterprise Fleet

QPU Cluster Orchestration

Multi-processor orchestration software for enterprises with dedicated cloud QPU reservations. Automatically dispatches complex workloads to the optimal physical backend based on live coherence conditions.

Tier 3 · Infrastructure OEM

Hardware Platform Hypervisor

Licensing the Prometheus hypervisor directly to quantum hardware manufacturers and cloud brokers (AWS Braket, Azure Quantum, IBM Quantum) as an embedded, native pre-execution layer.

Strategic Financing

Capital Allocation: Scaling Compute and Production Access

The core execution intelligence engine is complete, documented across 33 IBM QPU deployments, and proven on real hardware. We are raising seed capital to expand multi-architecture hardware coverage, onboard external enterprise pilot workloads, and harden our high-throughput API gateway.